 HexaPDF
Analysing PDFs
This how-to guide shows how to use the hexapdf inspect command to analyse PDF files.
How hexapdf inspect Works
The hexapdf command line tool comes with a variety of sub-commands, one of them being the
inspect command. This command is designed to allow its user to inspect and analyse a PDF file.
The default mode is the interactive mode which is used when no command line arguments besides the PDF file are given. The interactive mode loads the PDF file and allows running one or more commands against it which is useful if the PDF file in question is huge.
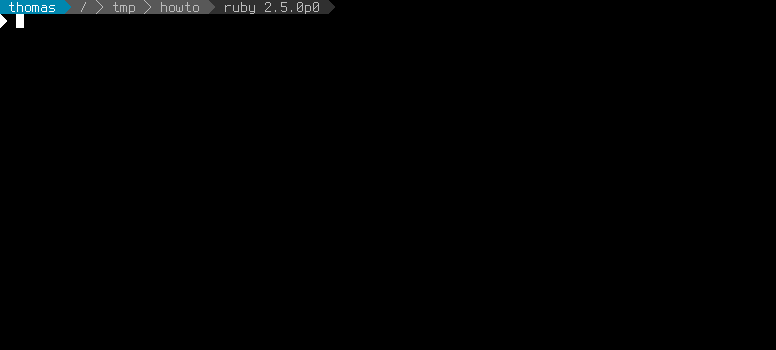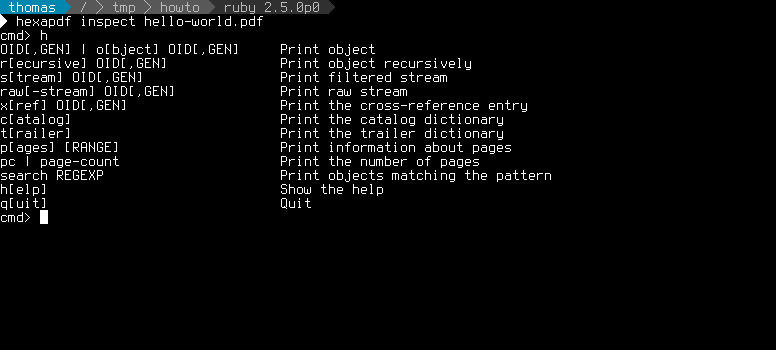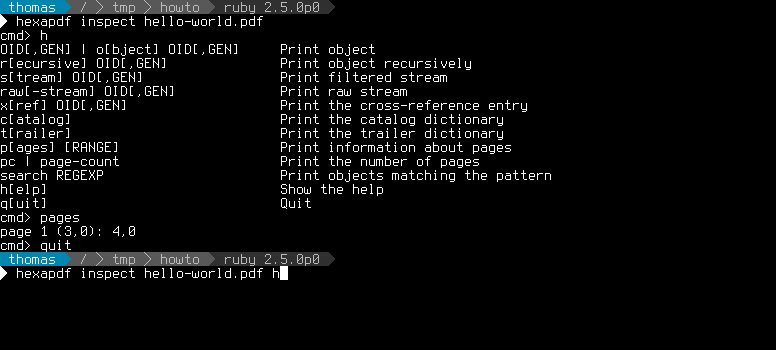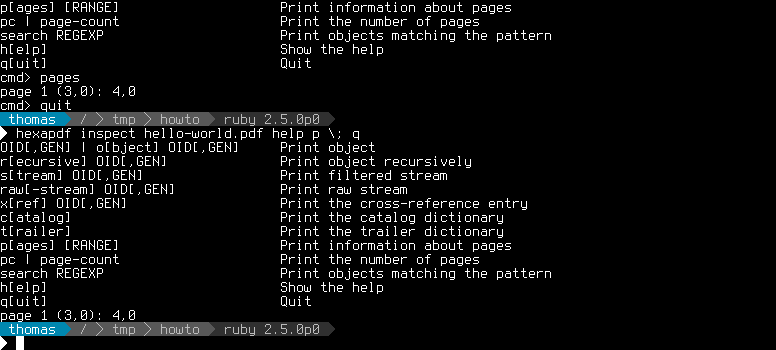
If additional arguments are provided on the command line, they are interpreted as interactive mode commands and executed.
Let’s see those two ways of running hexapdf inspect in action:
-
First we invoke the interactive mode and run three commands:
hfor showing the help,pagesfor displaying all pages andquitfor quitting the interactive mode. -
Then we use command line arguments to run the same three commands (although
quitwouldn’t be necessary). Note how we have to add a semicolon (escaped because otherwise it would be interpreted by the shell) after thepagescommand as command separator because otherwise it would useqas argument.
That’s all the needed basics, let’s dive into various usage scenarios and explore the inspect
command’s functionality.
Traversing the PDF Tree Structure
The key topic on PDF’s document structure explains the main structures used in PDF files. Basic knowledge of the places where certain information can be found is useful when analysing PDF files.
The trailer, object, catalog and stream commands can help you navigate through this tree
structure by showing the objects in question. Let’s see them in action:
-
The
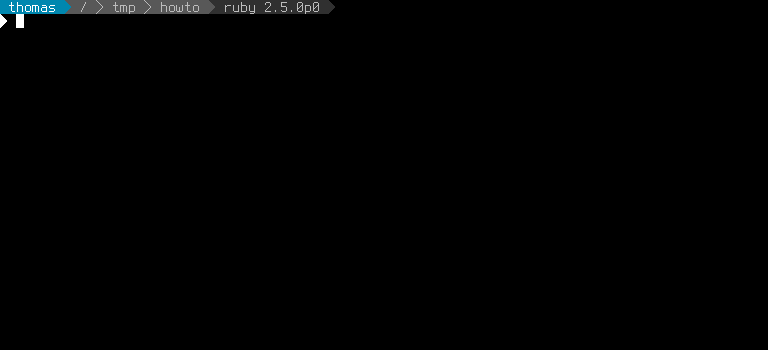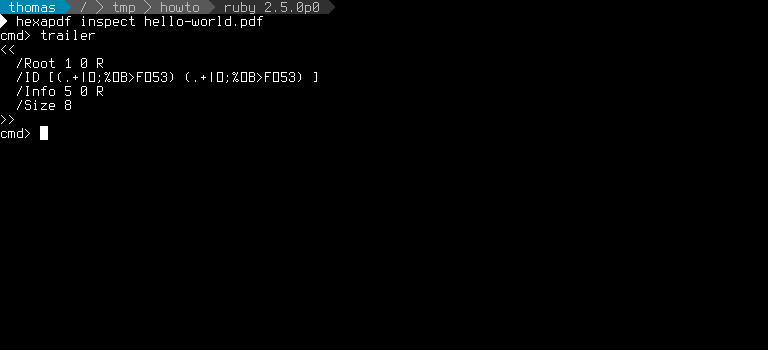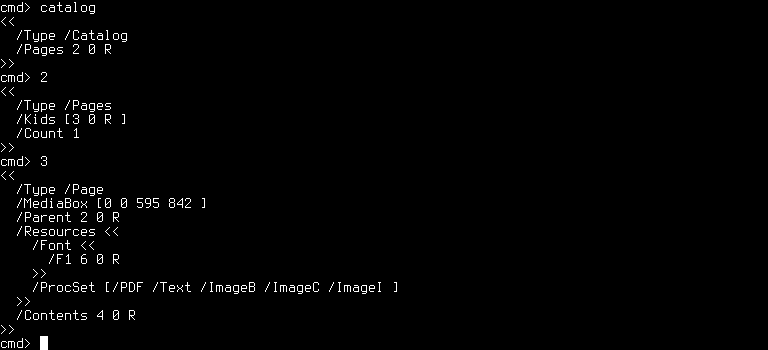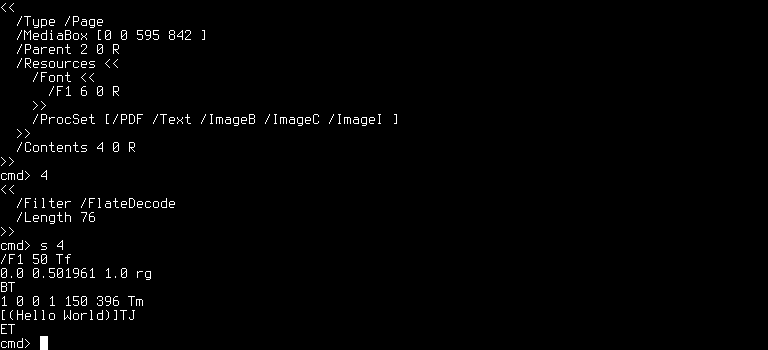
trailerortcommand shows the trailer dictionary. This dictionary may have an associated object identifier but since that is not always the case this special command is available.Interesting objects in the trailer dictionary are the
/Infodictionary with basic meta data, the/Encryptiondictionary with encryption information and the catalog dictionary under the/Rootkey containing the main PDF objects. -
Next we use the short form of the
objectcommand by just providing the object number referenced in the/Rootentry. This will show us the catalog dictionary. We then use thecatalogcommand to show the same object. So if you want to start at the catalog, its faster to use the providedcatalogcommand. -
Finally we navigate through the page tree, which only contains one page, and then show the contents of the page - more on that below.
The used sample PDF is very simple, in normal PDFs the catalog dictionary contains many more keys for various things like annotations or form fields.
Another way to view the tree structure of a PDF is to use the recursive command. This command will
not only show the requested object but also all objects referenced from it. Note that this will
often show you the whole document tree when one page is referenced since page nodes have a reference
to their parent. See Comparing PDF Files below for details.
Analysing Pages
In the last section you got a glimpse at inspecting pages, by navigating from the catalog
dictionary. Since inspecting pages is often necessary the special pages command exists. It will
display all page object identifiers in the correct order, together with the object identifiers for
their content streams:
-
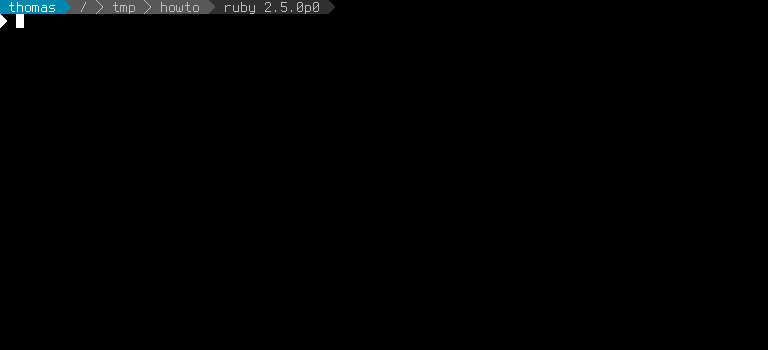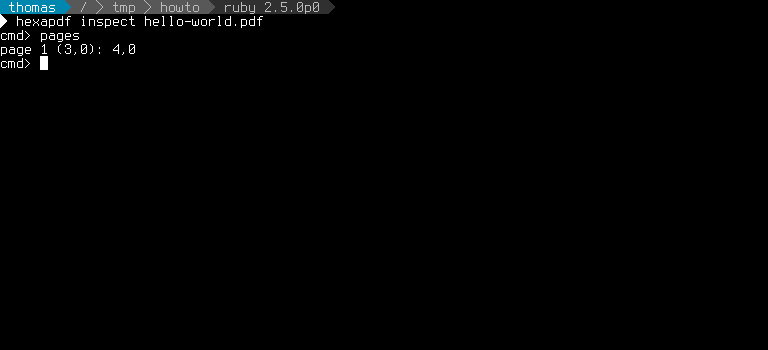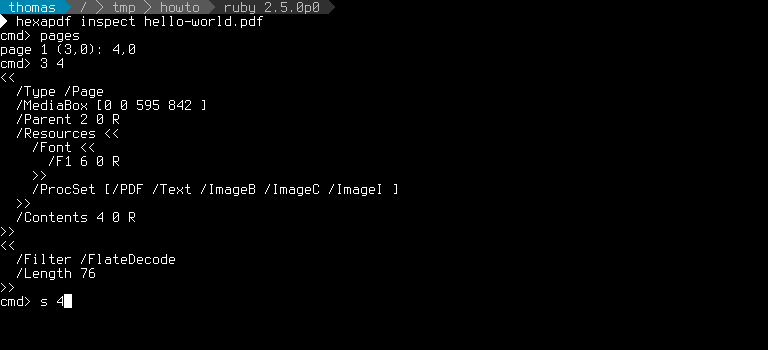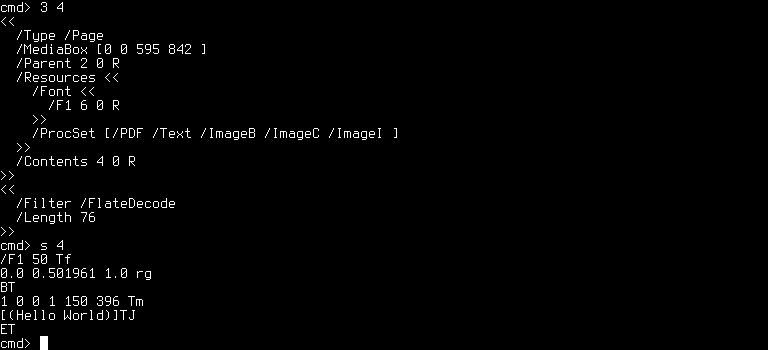
In the example you can see that the PDF file has one page and that the page has one content stream. Using two
objectcommands at once we show the respective objects. -
From the page object we see that the page has size A4 (the
/MediaBoxkey and knowing that the numbers represent PDF points with 72 points per inch) and that it references (but may not actually use) one font (in the/Resources→/Fontdictionary). -
The stream object itself is rather plain, the interesting part is the stream contents. A page’s content stream is written with the same syntax as a PDF file and contains the render instructions for the viewer.
Since we use a very simple PDF as example (see the tutorial “Creating a PDF Document from Scratch” for how it was created), deciphering the instructions is not that hard:
- The first line selects a font from the resource dictionary and sets the font size to 50 points.
- The second line sets the “text color” (actually the fill color) to an RGB value of
(0, 128,
255)
. - The next four lines draw the text “Hello World” at the location (150, 396).
Page objects often contain much more information, for example references to image resources, annotations or form fields.
Searching for Data
Sometimes you need to find an object with some specific data in it. For example, when an error message provides the name of a dictionary key or (part of) a value. Or when you want to find all objects referencing a specific indirect object.
In such cases the search command comes in handy: It searches through all indirect objects and
prints those matching the given argument (a regular expression). Here is an example:
-
First we search for occurrences of “hexa”, finding the information dictionary where the search string appears under the
/Producerkey. -
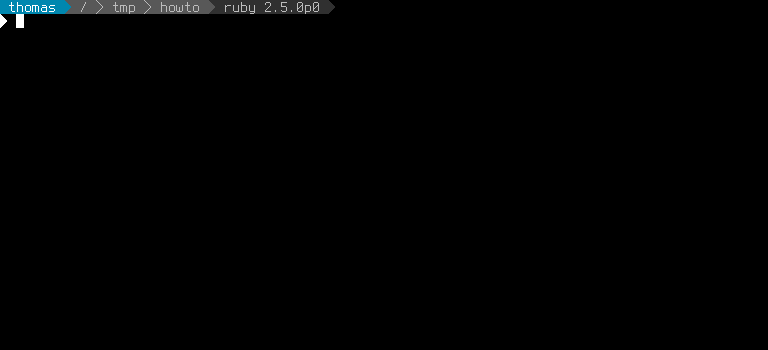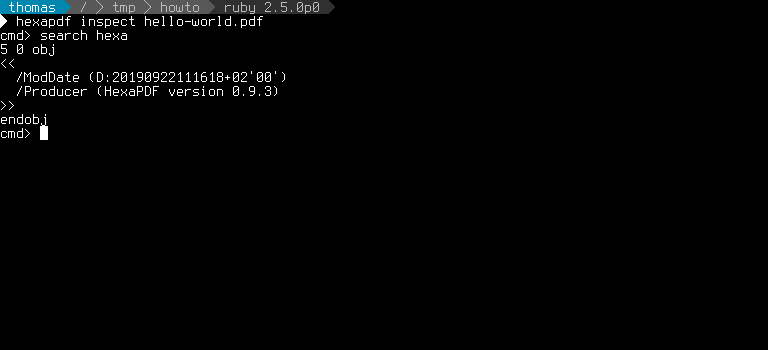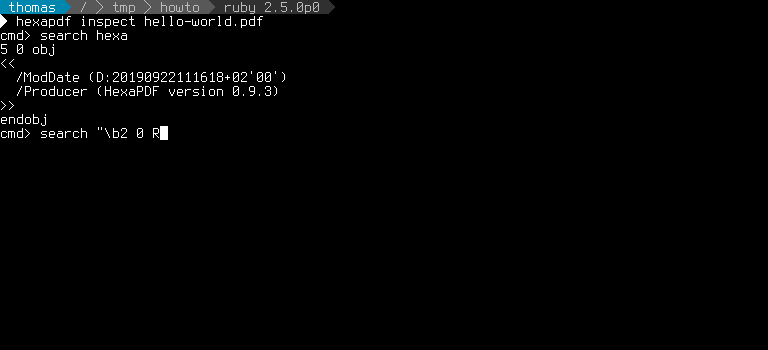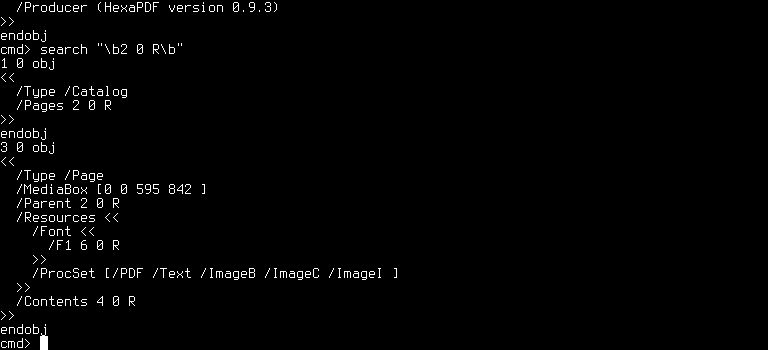
Then we search for all references to the indirect object (2,0) by using the search string
\b2 0
R\b
(in this case it is important to use the\banchors for word boundaries). This results in two objects being shown, the catalog dictionary and the dictionary of the only page, because the object (2,0) refers to the root of the page tree.
Comparing PDF File Structure
Comparing the structures of two PDF files allows you to analyse “behind the scenes” changes done by a program. If you want to compare two PDF files visually, i.e. the appearance of the page content, we recommend using a tool like DiffPDF.
To compare PDF structures use the recursive command to output the whole structure of the PDFs in
question and then compare the output. By using the process substitution feature of the shell you
don’t even need to create temporary files.
Here is a simple example showing the difference between the hello-world.pdf we have used
throughout this guide and the optimized version:
-
First we produce the optimized version using the
hexapdf optimizecommand which compresses the PDF down to about 50% of the original file size. -
Then we use the
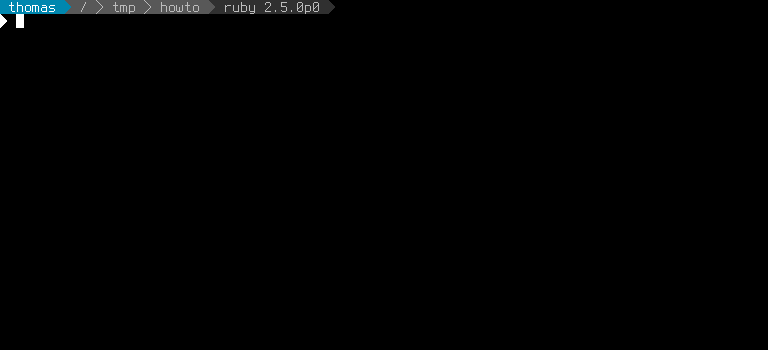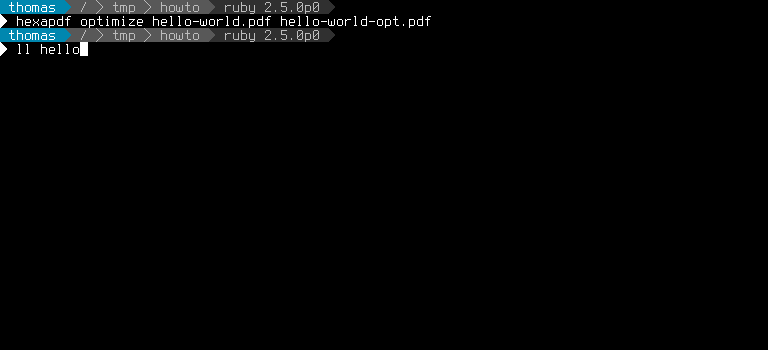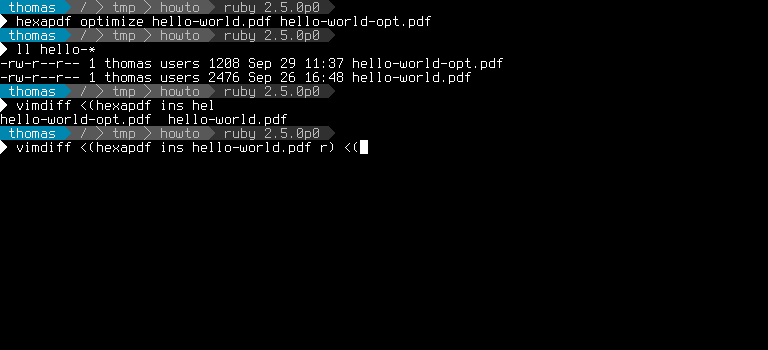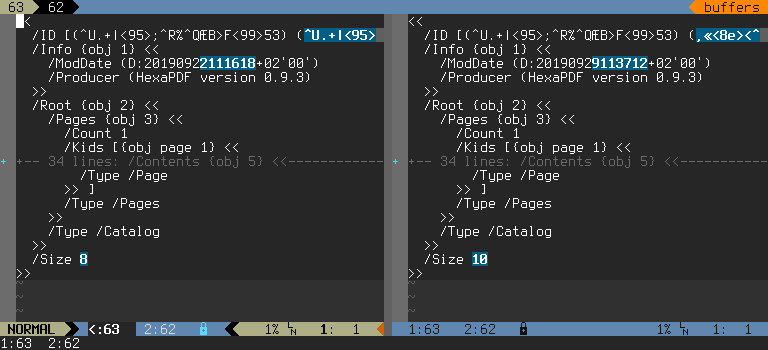
recursivecommand inhexapdf inspect’s command line mode forhello-world.pdfandhello-world-opt.pdfand use their output directly withvimdiffto show the differences. -
There are only three differences shown:
-
The second part of the
/IDkey changed. This is expected as this part should always change when an existing file is modified. -
The
/ModDatefield also changed to reflect the date of the change. -
And although the file is smaller now it contains two more objects: one cross-reference stream and one object stream. These stream objects are never referenced from the main structure since they only provide a different way of storing data in the PDF file. Therefore they also don’t appear in the
recursiveoutput.
If the PDF file was created by another program and not HexaPDF, the
/Producerline would also have changed. -
-
The meaning of this is that nothing essential really changed when the PDF file was optimized, which was expected.
If you try this with bigger files and ones not created with HexaPDF, the output will probably show many more changes because HexaPDF also removes unneeded key-value pairs of dictionaries.